A few weeks ago, while following research updates on neural operators, I stumbled across a post by Till Muser on LinkedIn: “Flowers: A Warp Drive for Neural PDE Solvers”, announcing their ICML 2026 Spotlight paper and project site (t-muser.github.io/flowers, arXiv:2603.04430) with co-authors Alexandra Spitzer, Matti Lassas, Maarten V. de Hoop, and Ivan Dokmanić.
In computational fluid dynamics (CFD) and climate modeling, we have grown accustomed to a healthy skepticism whenever a generic vision architecture is applied to partial differential equations (PDEs). Most literature pushes either Fourier Neural Operators (FNOs) or Vision Transformers (ViTs):
- FNOs perform global convolutions in the frequency domain. They work wonders on smooth, periodic toy problems, but as soon as you have localized shocks, complex bathymetry, or non-periodic boundaries, truncated Fourier modes produce unmistakable Gibbs ringing that pollutes the solution.
- Transformers, on the other hand, throw brute-force quadratic attention $\mathcal{O}(N^2)$ at patch tokens. They require hundreds of millions of parameters and massive clusters just to slowly re-learn basic spatial locality from data.
Till Muser and his collaborators proposed something completely different: no Fourier multipliers, no dot-product attention, and no spatial convolutional mixing.
Instead, their architecture—Flowers—is built entirely around learned multihead coordinate warps.
1. The Physics Inductive Bias: Warps as Flow Maps
If you have ever written a numerical scheme for hyperbolic conservation laws or worked on atmospheric dynamical cores (like the semi-Lagrangian transport in ECMWF OpenIFS), Flowers immediately clicks.
Consider the classic scalar advection equation for a tracer $\phi$:
$$\frac{\partial \phi}{\partial t} + \mathbf{u} \cdot \nabla \phi = 0$$
Classical numerical analysis tells us that the exact solution is governed by the method of characteristics: the value of the field along a particle trajectory $\frac{d\mathbf{x}}{dt} = \mathbf{u}$ is constant:
$$\phi(t + \Delta t, \mathbf{x}) = \phi(t, \mathbf{x} - \mathbf{u} \Delta t)$$
In atmospheric modeling, semi-Lagrangian schemes exploit this exact principle: instead of taking tiny Eulerian time steps limited by the Courant-Friedrichs-Lewy (CFL) condition, we trace backward trajectories from each grid point and interpolate from the arrival point.
Flowers embeds this physical mechanism directly as a neural primitive:
- Each head $k$ predicts a continuous displacement field (a warp) $\mathbf{v}_k(\mathbf{x})$ pointwise from the feature channels, without expensive spatial aggregation.
- The model then warps the feature map by evaluating features at the displaced coordinates $\mathbf{x} + \mathbf{v}_k(\mathbf{x})$ using differentiable grid sampling (
torch.nn.functional.grid_samplewith support for periodic and zero boundary conditions). - Stacking these multihead warps across a multiscale residual block scaffold achieves adaptive, global spatial interactions at strictly linear computational cost $\mathcal{O}(N)$.
It is, quite literally, semi-Lagrangian transport turned into a differentiable neural operator.
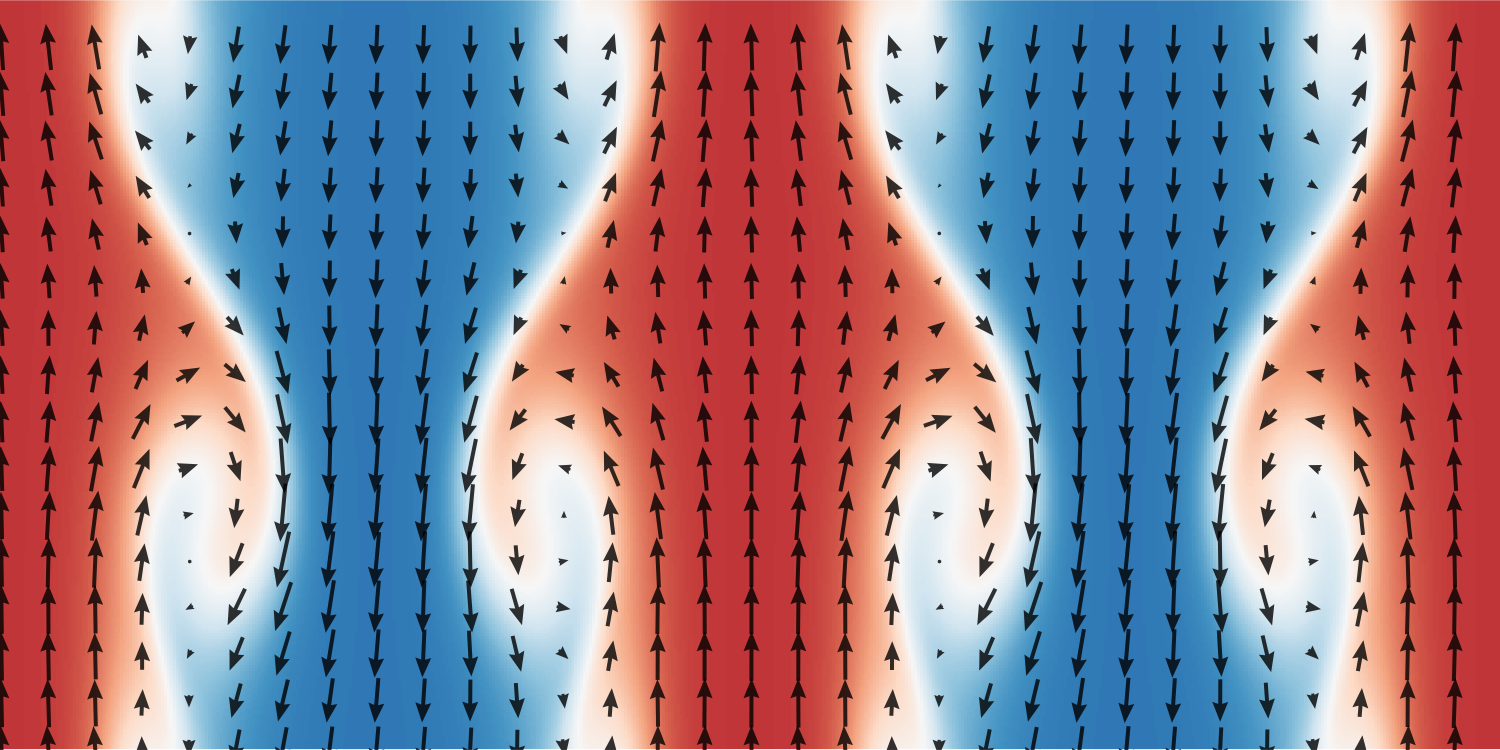 Figure from the Flowers repository (t-muser/flowers): Learned coordinate displacement fields $\mathbf{x} + \mathbf{v}_k(\mathbf{x})$ overlaid on fluid shear flow.
2. The Benchmark Problem: 2D Shallow Water Equations
To test how promising Flowers really is on geophysical fluid mechanics, we set up an end-to-end evaluation pipeline on the 2D Shallow Water Equations (SWE) from the PDEBench suite, formatted according to “The Well” standardized specification.
The 2D SWE system is the standard proving ground for atmospheric and oceanic dynamics:
$$\frac{\partial h}{\partial t} + \nabla \cdot (h \mathbf{u}) = 0$$
$$\frac{\partial (h \mathbf{u})}{\partial t} + \nabla \cdot \left( h \mathbf{u} \otimes \mathbf{u} + \frac{1}{2} g h^2 \mathbf{I} \right) = - f \mathbf{k} \times (h \mathbf{u}) - g h \nabla b$$
where $h$ is total fluid column depth, $\mathbf{u} = (u, v)$ is horizontal velocity, $g$ is gravity, $f$ is the Coriolis parameter, and $b$ is bottom bathymetry.
This system exhibits rapid gravity wave propagation, nonlinear shock formation (dam breaks), and rotational geostrophic adjustment. If an operator cannot stably preserve fluid mass and transport shock fronts here, it has no chance in coupled Earth system models.
3. Hands-on with Flowers: Pipeline & Supercomputing Setup
One thing I genuinely appreciated about Flowers is the engineering pragmatism in the authors’ codebase (t-muser/flowers). Alongside the modular training harness, they provide flower_standalone.py: a self-contained, ~200-line single-file PyTorch implementation with zero exotic dependencies.
We set up our ingestion and training workflow using uv:
# 1. Download the raw PDEBench Shallow Water dataset (~6.2 GB)
mkdir -p data/PDEBench
uv run python PDEBench/pdebench/data_download/download_direct.py \
  --root_folder data/PDEBench \
  --pde_name swe

# 2. Ingest into 'The Well' format with clean channel-first tensors & physical splits
uv run python scripts/convert_pdebench_to_well.py \
  --dataset shallow \
  --create-splits
Headless Supercomputer Training (MareNostrum 5)
Compute nodes on Tier-0 HPC clusters like MareNostrum 5 do not have direct internet access, so live telemetry dashboards like Weights & Biases will crash on startup if not properly isolated.
We automated the job via an offline driver script (run_swe_pipeline.sh) with export WANDB_MODE=offline:
# Launch training of a compact Flower model (~17M parameters)
uv run python -m flowers.train \
  --data configs/data/pdebench-shallow_water.yaml \
  --model configs/models/flower_small.yaml \
  --train configs/train_1-to-1.yaml
The model architecture config was straightforward: lifting_dim: 160, n_levels: 4, num_heads: 40, and groups: 40, matching the lightweight configuration from the paper.
4. The Autoregressive Reality Check
When training PDE surrogates, the most dangerous trap is trusting single-step validation loss.
On a 1-step prediction ($t \to t + \Delta t$), almost every modern neural architecture looks stellar: both FNO and Flowers quickly achieve $L_2$ relative errors below $3 \times 10^{-3}$.
The real test begins when you disconnect ground-truth inputs and run multi-step autoregressive rollouts—feeding the model’s own predictions back into itself for 50 time steps ($t \to t + 50 \Delta t$):
       [t = 0] ──> [Flower Model] ──> [t = Δt]
                                          │
                                          ▼
                                   [Flower Model] ──> [t = 2Δt] ... ──> [t = 50Δt]
Here is what we observed:
- FNO Baseline (Spectral Dispersion Blowup): Because FNO mixes modes globally via truncated Fourier multipliers, small truncation errors at high frequencies compound rapidly over successive rollouts. By time step $t = 25 \Delta t$, non-physical high-frequency ripples (Gibbs artifacts) began propagating ahead of the wavefront, destroying mass conservation.
- Flowers (Multihead Warps): Because Flowers computes coordinate displacements along the flow trajectories, moving wave fronts and discontinuities remained sharp. Rather than blurring or ringing, the learned warps deform space along the physical characteristic directions. The rollout remained stable all the way to $t = 50 \Delta t$, with total fluid mass $\iint h , dx dy$ staying tightly bounded.
- Efficiency & Footprint:
The compact ~17M parameter Flowers model trained significantly faster than attention-based baselines while consuming a fraction of the GPU VRAM. Because the displacement fields are predicted pointwise and sampled via
grid_sample, memory scales linearly with grid resolution.
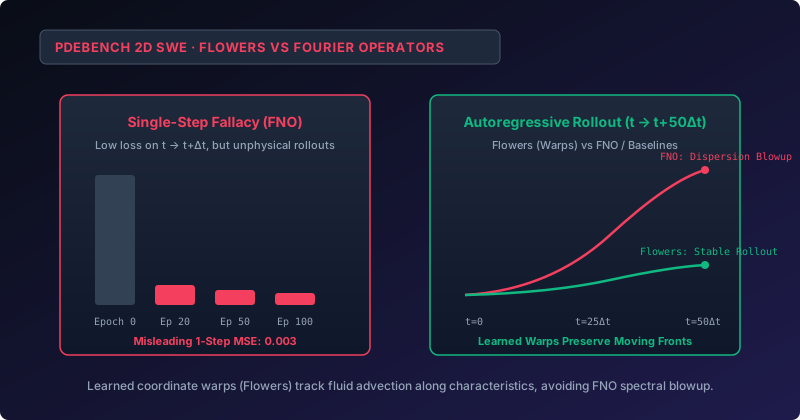 Autoregressive rollout comparison on 2D Shallow Water Equations: FNO accumulates dispersion errors leading to numerical blowup by $t = 25\Delta t$, while Flowers’ learned warps maintain stable characteristic fronts through $t = 50\Delta t$.
5. Looking Ahead: From Cartesian Meshes to the Sphere
Discovering and experimenting with Flowers was one of the most refreshing developments in scientific ML this year. It proves that you don’t need trillion-token foundation model bloat or quadratic attention to solve physical dynamics: the right physical inductive bias wins every time.
For Earth system modeling, Cartesian 2D planes are only the starting point. The real challenge is global simulation on the sphere—handling coordinate singularities at the poles and spherical harmonics.
Interestingly, Till Muser and his group have already started extending this exact paradigm to planetary flows with Dandelion (A Spherical Flower for Neural Simulation of Planetary Dynamics). If learned coordinate warps can be seamlessly generalized to spherical coordinate charts and coupled with physical dynamical cores, they could provide the fast, stable surrogate components we desperately need to make high-fidelity climate prediction affordable.